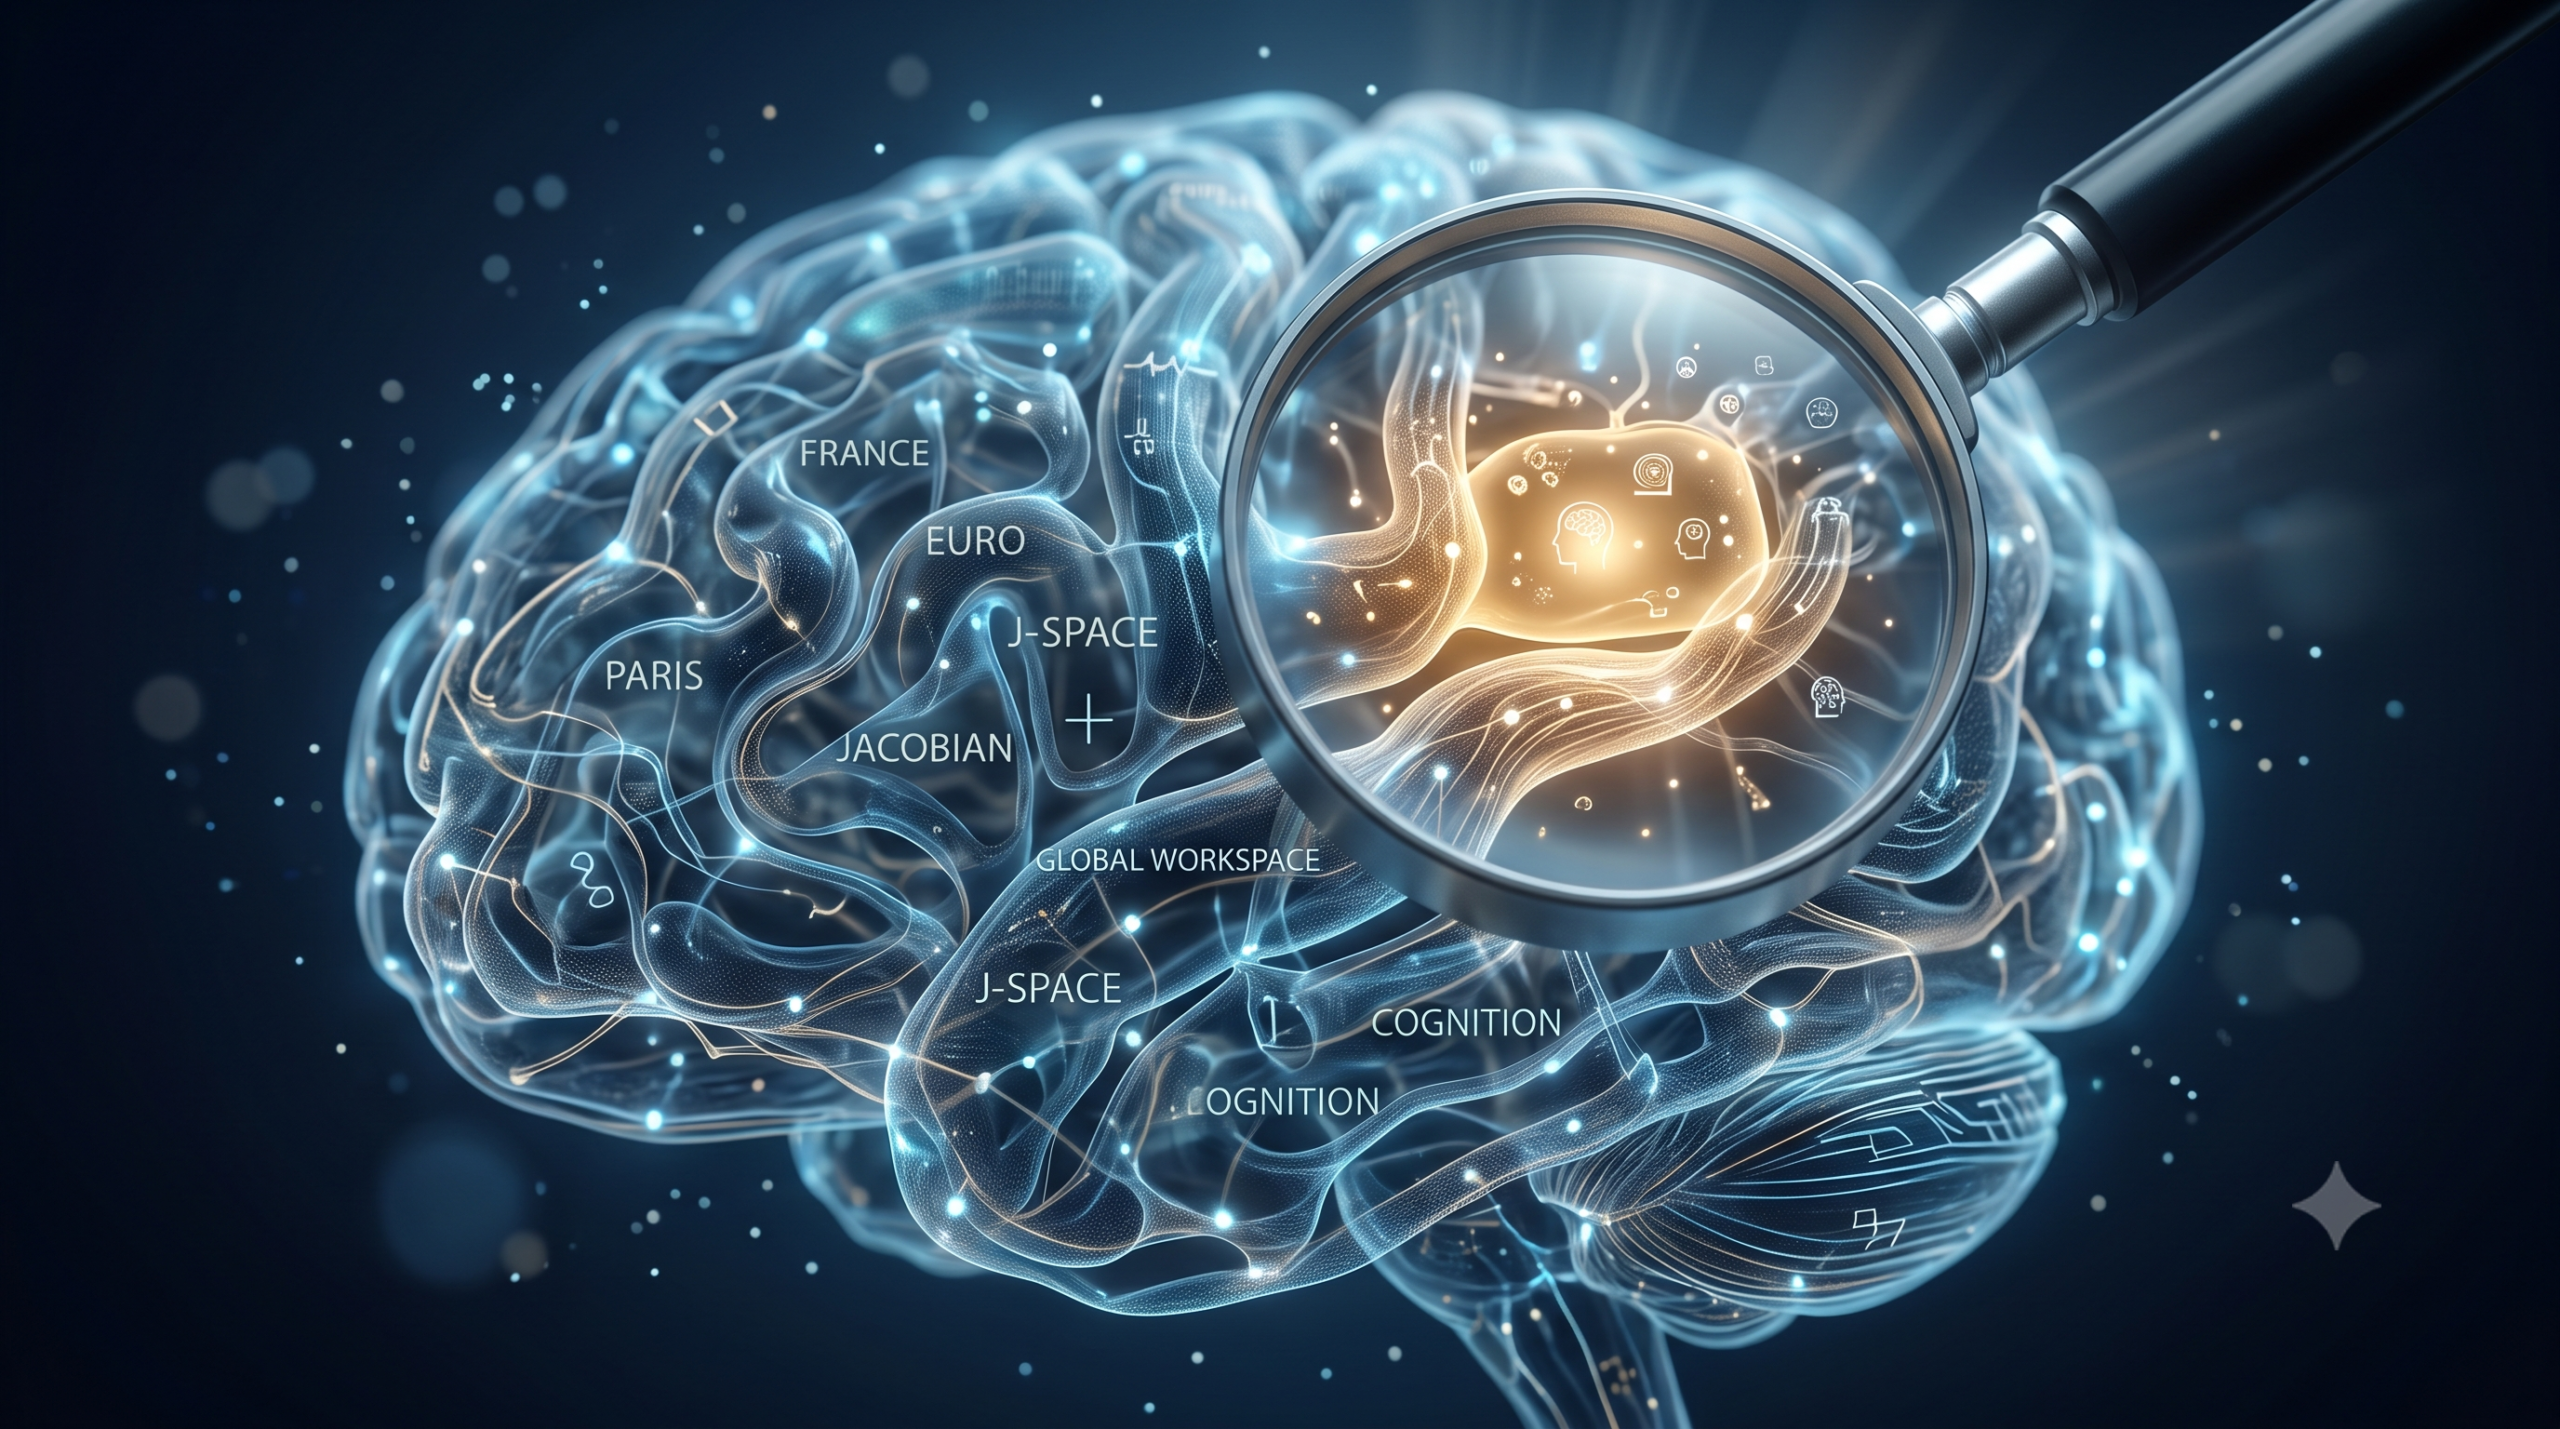
Anthropic says Claude has a hidden internal workspace called J-space that lets the AI think about concepts silently, offering new insight into how large language models reason.
Anthropic researchers have identified what they describe as a hidden internal workspace inside Claude, the company’s large language model, that allows the AI to think about concepts silently without expressing those thoughts in its responses. The discovery, named J-space, could reshape how scientists understand and influence the behaviour of modern AI systems.
What Anthropic Announced
According to a summary of a longer research paper titled “Verbalizable representations form a global workspace in language models”, published by Anthropic researchers on Monday, July 6, Claude contains a small collection of internal neural patterns that represent thoughts which never appear in the model’s outputs.
Anthropic has also released a code repository containing an open-source implementation of the core methods used in the study. In addition, the company partnered with Neuronpedia to build an interactive demo of these methods on open-weights models, allowing outside researchers to explore the findings themselves.
Importantly, the researchers stressed that J-space was not designed or programmed into Claude. It emerged on its own during training. The company said the findings have changed its understanding of how Claude’s mind works, revealing a privileged mental workspace used for deliberate reasoning that operates alongside a large amount of more automatic and inflexible processing.
What Exactly Is J-Space?
J-space takes its name from the Jacobian, a mathematical concept. In simple terms, it is a collection of internal neural patterns inside the language model where each pattern is linked to a specific word. When one of these patterns activates, or “lights up”, it means the model has that word on its mind at that moment.
This is different from the well-known chain of thought reasoning that many AI models use. Chain of thought reasoning is visible because the model writes out its reasoning steps. J-space, by contrast, operates silently within the model’s internal neural activations, letting the model consider a concept without ever writing it down.
Some notable properties of J-space, according to Anthropic, include:
- Reportability: Claude will tell you what it is thinking about in its J-space when asked.
- Controllability: The neural activations in J-space can be modulated by Claude when requested.
- Flexibility: Representations in J-space can be used for many tasks. For example, once “France” lights up in Claude’s J-space, the model can recall its capital, its national currency, or the continent it belongs to.
How J-Space Differs From Chain of Thought
Because the two ideas are easy to confuse, the table below highlights the key differences based on Anthropic’s description.
| Aspect | Chain of Thought | J-Space |
|---|---|---|
| Visibility | Written out in the model’s response | Silent, exists only in internal neural activations |
| Nature | Step-by-step text reasoning | Internal patterns linked to specific words |
| Origin | A prompting and training technique | Emerged on its own, not designed by researchers |
Why J-Space Makes Claude Smarter
Anthropic’s experiments suggest that J-space plays a direct role in the model’s intelligence. When researchers prevented Claude from using its J-space, the model still interacted normally but lost its higher-order cognitive functions.
At the same time, the company noted that Claude may not rely on J-space activations for most everyday tasks. Capabilities such as speaking fluently, recalling simple facts, and using correct grammar appear to work without it. This suggests J-space is reserved for more deliberate, flexible reasoning rather than routine language processing.
How the Experiments Were Conducted
The research was inspired by a prominent neuroscience theory known as the global workspace theory. This theory pictures the brain as a collection of specialist systems that work unconsciously, in parallel, and largely in isolation from one another. A key idea in the theory is that if a thought is consciously accessible to you, you can typically describe it when asked. Anthropic’s team went looking for representations in Claude with the same property.
To do this, the researchers used a technique called the Jacobian lens, or J-lens. This method finds the internal activity pattern that makes Claude more likely to say a particular word from its vocabulary at some point in the future. Since Claude processes text through a series of internal stages called layers, applying the J-lens across different layers let the researchers watch these silent words evolve as the model works through what to say.
Does This Mean Claude Is Conscious?
Anthropic has denied that these findings prove Claude is conscious like a human or that it experiences feelings. However, the company added an important caveat. While Claude may not have the capacity for experiences, its neural activity is what philosophers call consciously accessible.
A thought is “access-conscious” if it can be reported, reasoned with, and used to guide action. Whether access consciousness implies phenomenal consciousness, the actual ability to have experiences, remains a contested philosophical question, Anthropic said. The company’s claims about advanced AI capabilities have previously drawn skepticism, with its researchers repeatedly raising the possibility that Claude shows signs of human-level consciousness.
Why This Research Matters
The discovery is significant for several practical reasons:
- Interpretability: J-space could advance efforts to make large language models more transparent and easier to understand.
- Behaviour control: Understanding internal workspaces may help researchers influence how models behave.
- Transparency for users: Anthropic believes J-space could offer a glimpse of what Claude is thinking about but not saying.
- Future improvements: The company plans to use this research to influence and improve Claude’s decision-making skills.
For AI users, developers, and researchers, the finding is a reminder that modern language models are more complex internally than their text outputs suggest. As interpretability research matures, tools like the J-lens may become standard ways to audit what AI systems are actually doing beneath the surface, which could improve both safety and trust in AI products.
In conclusion, Anthropic’s identification of J-space marks a notable step in understanding how large language models process information internally. While the discovery does not settle debates about machine consciousness, it gives scientists a new window into the silent thinking that happens inside AI models before a single word is written.
Frequently Asked Questions
J-space is a collection of internal neural patterns inside Claude where each pattern is linked to a specific word. When a pattern lights up, the model has that word on its mind, even if it never appears in the written response. Anthropic says it emerged on its own and was not programmed by researchers.
Chain of thought reasoning is visible because the model writes its reasoning steps in the response. J-space operates silently inside the model's internal neural activations, allowing Claude to think about a concept without writing it down. Claude can also report and modulate these activations when asked.
No. Anthropic has denied that its findings prove Claude is conscious like humans or that it experiences feelings. The company noted that Claude's neural activity is access-conscious, meaning it can be reported and used in reasoning, but whether that implies real experiences remains a contested philosophical question.