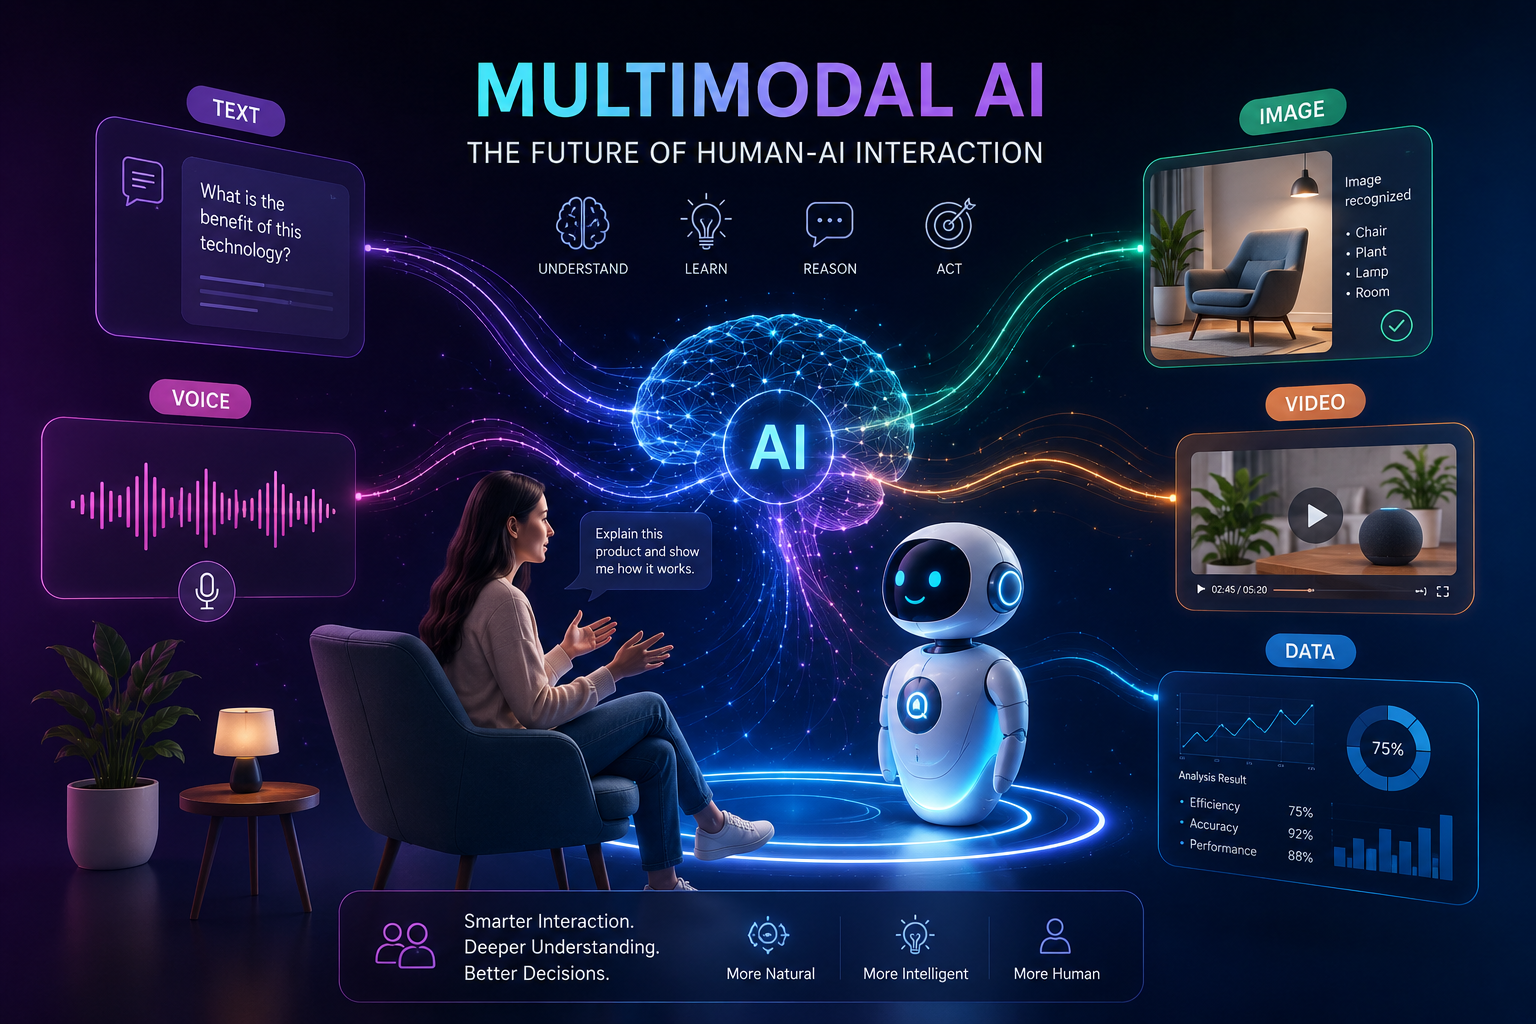
Artificial intelligence is no longer limited to reading text or recognising images in isolation. A new generation of AI systems can now process text, images, audio, and video all at once — and respond in ways that feel far more natural and intelligent. This technology is called Multimodal AI, and it is quickly becoming one of the most significant shifts in how humans interact with machines.
What Is Multimodal AI?
Multimodal AI refers to artificial intelligence systems that can understand and process multiple types of data simultaneously. Traditional AI models were built to handle only one kind of input — either text, or images, or sound. Multimodal AI breaks that barrier.
Consider a practical example: you upload a photo of a damaged machine part and type the question, “What is wrong with this equipment?” A multimodal AI system reads your text, analyses the image, and combines both inputs to give you a precise, useful answer. That kind of combined understanding was not possible with older AI systems.
The key types of data multimodal AI can work with include:
- Text — written messages, documents, reports
- Images — photographs, screenshots, scans
- Audio — voice recordings, speech, sound signals
- Video — live feeds, recorded clips, surveillance footage
- Sensor data — readings from machines, wearables, and IoT devices
Why Multimodal AI Matters Right Now
Humans naturally communicate using a mix of speech, visuals, gestures, and written words. Traditional AI systems could only handle one channel at a time, which made interactions feel rigid and limited. Multimodal AI closes that gap by processing information the way humans actually experience the world.
This is why technology companies, healthcare providers, manufacturers, and educators are all investing in multimodal AI solutions. The ability to understand context from multiple sources makes AI responses more accurate, more relevant, and more helpful.
Some of the core benefits include:
- Better contextual understanding — AI can cross-reference inputs to avoid misinterpretation
- More natural user experiences — users can interact through voice, images, or text without restrictions
- Higher accuracy — multiple data sources reduce the chance of errors
- Faster automation — complex tasks like document analysis or video monitoring can be handled with less human involvement
- Greater accessibility — people who struggle with typing can use voice or images instead
Real-World Applications Across Industries
Multimodal AI is already being used across several sectors, and its impact is growing rapidly.
| Industry | How Multimodal AI Is Being Used |
|---|---|
| Healthcare | Analysing medical images, lab reports, and patient records together to speed up diagnosis |
| Customer Service | Processing text messages, screenshots, and voice notes to resolve issues faster |
| Manufacturing | Combining camera feeds, sensor data, and machine logs to detect defects and predict maintenance |
| Education | Delivering personalised learning through text, video, and voice-based interactions |
| Autonomous Vehicles | Analysing camera images, sensors, maps, and traffic data in real time for safe navigation |
In healthcare, multimodal AI helps doctors identify diseases faster by combining visual scans with written patient histories. In manufacturing, it reduces costly downtime by predicting equipment failures before they happen. In education, students benefit from personalised content that adapts to how they learn best.
Challenges That Still Need to Be Addressed
Despite its promise, multimodal AI comes with real challenges that organisations must consider before adopting it.
- High computing costs — processing multiple data types simultaneously demands significant hardware and infrastructure investment
- Privacy and security risks — multimodal systems often handle sensitive data including personal images, voice recordings, and medical information
- Technical complexity — accurately combining and interpreting different data formats is still a difficult engineering problem
- Data quality requirements — the system is only as good as the data it receives; poor-quality inputs lead to unreliable outputs
Researchers and technology companies are actively working to make multimodal AI more efficient, affordable, and secure. Progress is steady, and many of these barriers are expected to reduce significantly over the next few years.
What the Future of Human-AI Interaction Looks Like
The next phase of AI will be far more interactive than what exists today. AI assistants will not just read your messages — they will understand what you are looking at, what you are hearing, and what you are feeling, all in real time.
Smart devices, wearable technology, autonomous robots, and digital assistants will become capable of understanding human needs without requiring users to follow strict commands or formats. Businesses will use multimodal AI to build better customer experiences, automate complex operations, and make smarter decisions with less manual effort.
As computing power grows and AI models become more refined, human-AI interactions will feel increasingly natural, personalised, and effective. Organisations that begin adopting multimodal AI today will have a clear advantage as this technology becomes the standard across industries.
Multimodal AI represents a genuine step forward in how machines understand the world. By processing text, images, audio, and video together, these systems can respond with a level of intelligence and context-awareness that older AI models simply could not achieve. From hospitals and classrooms to factories and customer support centres, multimodal AI is already delivering measurable results — and its influence will only grow from here.
Frequently Asked Questions
Multimodal AI is an artificial intelligence system that can understand and process multiple types of data at the same time, such as text, images, audio, and video. Unlike traditional AI that handles only one type of input, multimodal AI combines different data sources to understand context more accurately and respond more intelligently.
Multimodal AI is being used across several industries. In healthcare, it helps analyse medical images alongside patient records. In manufacturing, it monitors equipment using camera feeds and sensor data. In education, it personalises learning through text, video, and voice. In customer service, it processes messages, screenshots, and voice notes together to resolve issues faster.
The main challenges include high computing costs due to the need to process multiple data types simultaneously, privacy and security concerns when handling sensitive personal data, and the technical complexity of accurately combining different data formats. Researchers are actively working to make these systems more efficient and affordable.